
Model Training
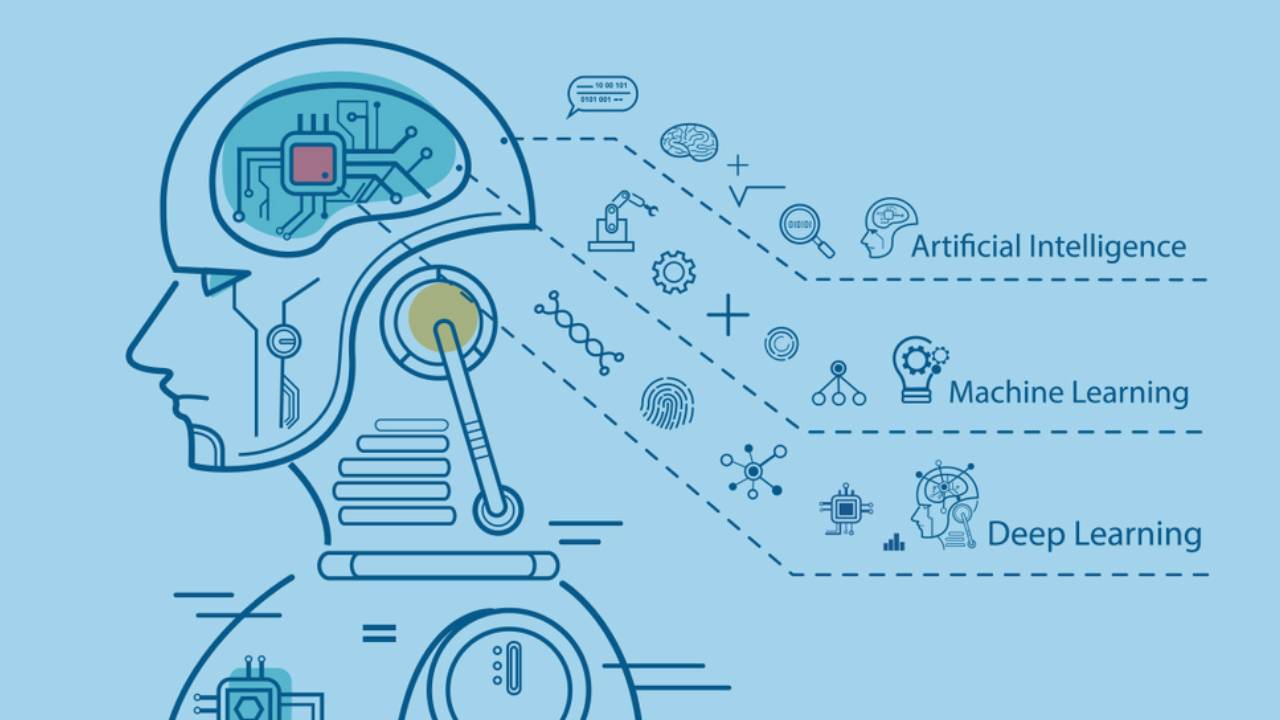
Train machine-learning models across large data sets, then inspect and fine-tune their performance for reliable results in production.
Models that learn from all your data
Training at big-data scale
Set algorithms that work across large sets of data to train your models, then inspect and fine-tune their performance.
Distributed training on the Hadoop ecosystem means your models learn from your complete history rather than a sample, and can be retrained on fresh data as your business changes.
What we deliver
From data preparation to a trained model you can deploy and trust.
Data Preparation
Select, clean and label training data, and engineer the features your model needs.
Supervised & Unsupervised Learning
Classification, regression, clustering and anomaly detection, matched to your problem.
Distributed Training
Train on full data sets with Apache Spark across a cluster instead of a single machine.
Model Tuning
Hyper-parameter tuning and feature selection to reach the best accuracy for your budget.
Evaluation & Inspection
Measure performance on held-out data and inspect results, so you know how the model behaves before go-live.
Trained Model & Retraining
Versioned, deployable models with scheduled retraining as new data arrives.
Machine learning in production since 2017
In 2017 a mobile operator asked us to screen the content of 120 million SMS a day, in real time, for fraud and phishing, in a language our team did not speak.
Machine learning made it possible, and we have been building ML and AI systems ever since. Today we bring the same experience to training models on our clients’ data at big-data scale.
Built on the Hadoop ecosystem
Training pipelines run on Apache Spark and YARN over HDFS and Delta Lake, with Apache Airflow scheduling every data-preparation, training and retraining run.
How we work
A repeatable training cycle that keeps your models accurate over time.
1. Prepare
Prepare your data and split it into training, validation and test sets.
2. Train & Tune
Train candidate models and fine-tune them against the metrics that matter to you.
3. Deploy & Retrain
Deliver the trained model into your application and keep it current with scheduled retraining.
Explore our Data & AI services
Each service stands on its own, and together they take you from raw data to AI in production.

Model Development
Predictive and machine-learning models for forecasting, scoring and anomaly detection, built on big data.
AI Model Training
Train and fine-tune deep-learning models and LLMs on our in-house GPUs, with data collected at scale.

Data Cleansing
Eliminate errors and inconsistencies with automated cleansing pipelines that keep your data reliable.